What Anthropic claims it found inside Claude’s thinking
You’ve probably seen the headline version: Anthropic says it can look “inside” Claude and find something like building blocks of thought—internal patterns that consistently light up for ideas such as places, people, code-related notions, or even more abstract themes. The claim isn’t that Claude has a secret English narration running in its head. It’s that, within the model’s internal activity, there appear to be stable directions or clusters that correlate with recognizable concepts across many different prompts.
The practical test is repeatability and control: when researchers identify one of these patterns, it should show up reliably in varied contexts, and nudging it should predictably change Claude’s output in the expected way. Even then, the finding is constrained by instrumentation and interpretation. You’re measuring a high-dimensional system through chosen probes, and “concept” is partly a human label placed on a messy signal.
A quick tour of “hidden spaces” without the math
Picture Claude mid-sentence: every word you’ve typed gets turned into a long list of numbers, and at each layer the model rewrites that list into a new list. Each rewrite is like moving a point around in a vast “hidden space”—not a map of English words, but a space where distance and direction reflect what the model currently treats as similar, relevant, or likely next. Two prompts that look different on the surface can land in nearby regions if they set up the same kind of situation (a request for a recipe, a debugging task, a refusal boundary).
When people say researchers “found” concepts in that space, they usually mean they found directions that, when the model’s internal state shifts along them, reliably tracks with something we recognize—say, “mentions of cities” or “Python error-fixing mode.” The catch is scale and ambiguity: there isn’t one clean “Paris neuron,” and many directions overlap, drift across layers, or only make sense under specific contexts. That’s why interpretability work leans so hard on repeated tests, not single striking examples.
How researchers tease out concepts from activation patterns
One common move is to treat the model like a black box you can still instrument: run thousands of prompts, record the internal activations, and ask which internal patterns best predict some label you care about. The label might be simple (“does the text mention a country?”) or behavioral (“is the assistant about to refuse?”). If a particular direction in activation space reliably separates “yes” from “no” across many varied examples, researchers tentatively call that direction a “feature” or “concept.”
Then comes the harder part: intervention. Instead of only observing, you nudge the model’s activations along that direction—amplify it, damp it, or swap it in—and check whether the output changes in the expected, specific way. Good signs are consistency across prompts and minimal collateral damage to unrelated content. Bad signs are brittle effects that vanish outside a narrow prompt set, or changes that look like generic “style” shifts. Even careful work is expensive: collecting datasets, storing activations, and running controlled ablations can cost serious compute and time.
What it means for Claude to “puzzle over” concepts
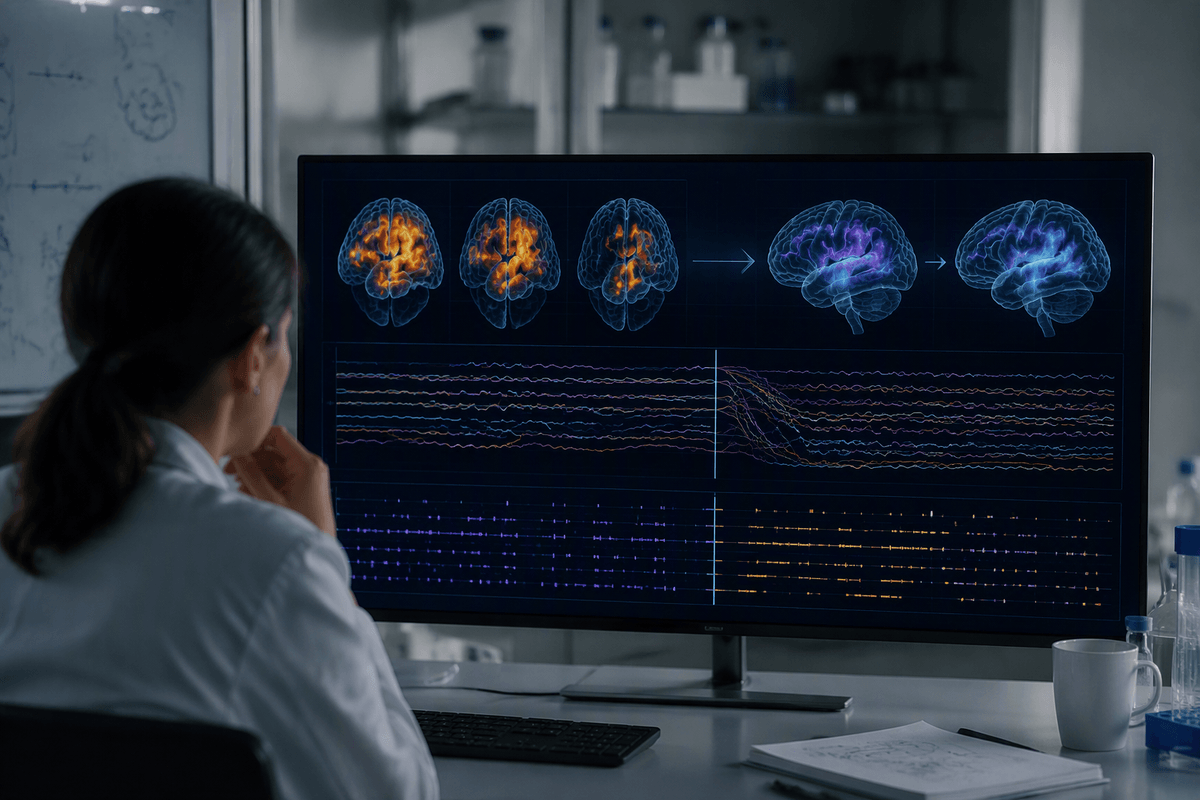
You can see what “puzzling over” means in moments where Claude’s answer changes direction mid-stream: it starts confidently, hits a conflict (two facts don’t line up, a policy boundary triggers, an instruction is ambiguous), and then revises. In activation-space terms, that looks less like a single “thinking” channel and more like a tug-of-war among partially compatible features—one pushing toward a direct answer, another toward caution, another toward a different interpretation of the question. The “puzzle” is the model settling into a region where the next-token predictions cohere again.
What matters is that this can be tested without pretending it’s introspection. If researchers can identify a small set of features that reliably rise during these revisions—say, uncertainty, constraint-checking, or refusal-prep—and then intervene to make the revision happen sooner or later, that’s evidence those features participate in the behavior. It still doesn’t prove Claude has a single, stable internal narrative, and it won’t work cleanly in every situation: many features are entangled, interventions can degrade fluency, and the compute cost of doing this across diverse prompts is high.
Why this discovery could improve safety and controllability
For safety teams, the appeal is straightforward: if you can reliably detect internal “refusal-prep,” “tool-use planning,” or “deception-risk” features before the model commits to an answer, you can build earlier tripwires than keyword filters or post-hoc classifiers. That could mean routing a response to a stricter policy, requiring a second model pass, or prompting the model to ask a clarifying question when its own activations show a conflict. For product teams, the same approach looks like debugging: when a model stubbornly misreads an instruction, you can test whether it ever enters the intended “mode” internally, rather than guessing from outputs alone.
Intervention is the bigger prize. If a feature is causal enough that dialing it up or down predictably shifts behavior, it becomes a control knob that can complement fine-tuning: soften jailbreak susceptibility without flattening the whole personality, or reduce overconfident answering by increasing the feature that correlates with uncertainty checks. These knobs may not be stable across tasks, versions, or languages, and running the measurements at scale adds real latency, engineering complexity, and compute cost.
Where the technique breaks: limits, artifacts, and overclaims
The analogy breaks down once an internal “feature” is treated as a literal piece of a model’s mind. Many learned directions are polysemantic, meaning the same internal pattern may correlate with France, EU regulation, or trip planning depending on the surrounding context. Assigning that pattern a single label may make an explanation easier to communicate, but it does not establish that the model represents one clean concept there. Results also depend heavily on the layer, prompt, and dataset. A direction that separates examples neatly in one setting may become much less distinct after changing the topic, language, or format, making a convincing demo a poor guide to everyday reliability.
Intervention introduces another source of ambiguity. Pushing an activation may behave more like injecting noise or altering the model’s effective temperature, leading to broad changes in tone, verbosity, or caution rather than a targeted shift in the behavior under investigation. Probes have similar weaknesses. They may pick up surface cues such as phrasing, specific tokens, or the model’s tendency to reproduce the labels used during training. A supposed “refusal” feature, for example, may partly reflect the presence of language associated with refusal prompts rather than a mechanism responsible for refusing.
Even genuine causal relationships may prove temporary. Model updates can change or remove the internal direction that an intervention depends on, so a control developed for one Claude version may no longer behave the same way in the next. Interpretability therefore brings an ongoing maintenance burden: findings need to be retested as models, prompts, and evaluation sets change rather than treated as a one-time key to the system’s behavior.
What to watch next: from cool demos to real tools
You’ll know this is turning into a tool, not a demo, when it works under boring conditions: messy real user prompts, multiple languages, tool-using agents, and frequent model updates. The immediate watch item is monitoring—cheap enough to run on live traffic, and calibrated so “feature lit up” actually predicts a specific failure mode (hallucination onset, policy evasion, instruction loss), not just a vague style shift.
The harder milestone is portable control: interventions that survive new Claude versions, don’t noticeably degrade helpfulness, and come with clear rollback paths when they misfire. Expect real costs: extra latency to record activations, storage and privacy handling for traces, and ongoing “concept drift” audits as the model and product surface change.